Helformer: an attention-based deep learning model for cryptocurrency price forecasting
Published in Mathematical & Computational Engineering Applications, Statistics, and Business & Management
🔍 Behind the Scenes: Methodology & Innovation
1. The Helformer Architecture
Helformer integrates three key components to outperform existing models:
-
Series Decomposition: Using Holt-Winters smoothing, we break price data into level, trend, and seasonality components (Fig. 1). This step isolates patterns that traditional Transformers might miss.
-
Multi-Head Attention: Unlike sequential models (e.g., LSTM), Helformer processes all time steps simultaneously, capturing long-range dependencies efficiently.
-
LSTM-Enhanced Encoder: Replacing the standard Feed-Forward Network with an LSTM layer improves temporal feature extraction.
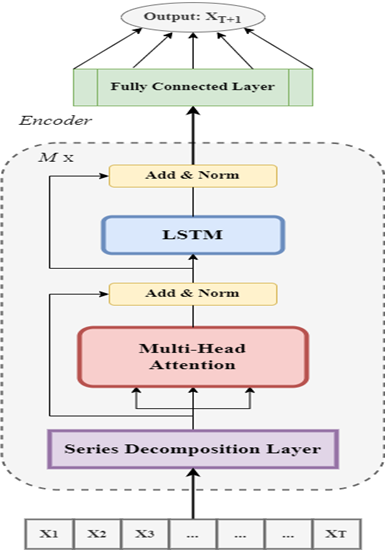
Fig. 1: Helformer architecture.
2. Data & Hyperparameter Tuning
We trained Helformer on Bitcoin (BTC) daily closing prices (2017–2024) and tested its generalization on 15 other cryptocurrencies (e.g., ETH, SOL). To optimize performance, we used Bayesian optimization via Optuna, automating hyperparameter selection (e.g., learning rate, dropout) and pruning underperforming trials early.
3. Evaluation Metrics
Helformer was benchmarked against RNN, LSTM, GRU, and vanilla Transformer models using:
-
Similarity metrics: R², Kling-Gupta Efficiency (KGE), EVS
-
Error metrics: RMSE, MAPE, MAE
-
Trading metrics: Sharpe Ratio, Maximum Drawdown, Volatility, Cumulative returns
💡 Key Findings & Practical Impact
1. Superior Predictive Accuracy
Helformer achieved near-perfect R² (1.0) and MAPE (0.0148%) on BTC test data, outperforming all baseline models (Table 1). Its decomposition step reduced errors by 98% compared to vanilla Transformers.
Table 1: Model Performance Comparison
|
Model |
RMSE |
MAPE |
MAE |
R² |
EVS |
KGE |
|
RNN |
1153.1877 |
1.9122% |
765.7482 |
0.9950 |
0.9951 |
0.9905 |
|
LSTM |
1171.6701 |
1.7681% |
737.1088 |
0.9948 |
0.9949 |
0.9815 |
|
BiLSTM |
1140.4627 |
1.9514% |
766.7234 |
0.9951 |
0.9952 |
0.9901 |
|
GRU |
1151.1653 |
1.7500% |
724.5279 |
0.9950 |
0.9950 |
0.9878 |
|
Transformer |
1218.5600 |
1.9631% |
799.6003 |
0.9944 |
0.9946 |
0.9902 |
|
Helformer |
7.7534 |
0.0148% |
5.9252 |
1 |
1 |
0.9998 |
2. Profitable Trading Strategies
In backtests, a Helformer-based trading strategy yielded 925% excess returns for BTC—tripling the Buy & Hold strategy’s returns (277%)—with lower volatility (Sharpe Ratio: 18.06 vs. 1.85), as shown in Fig. 2.
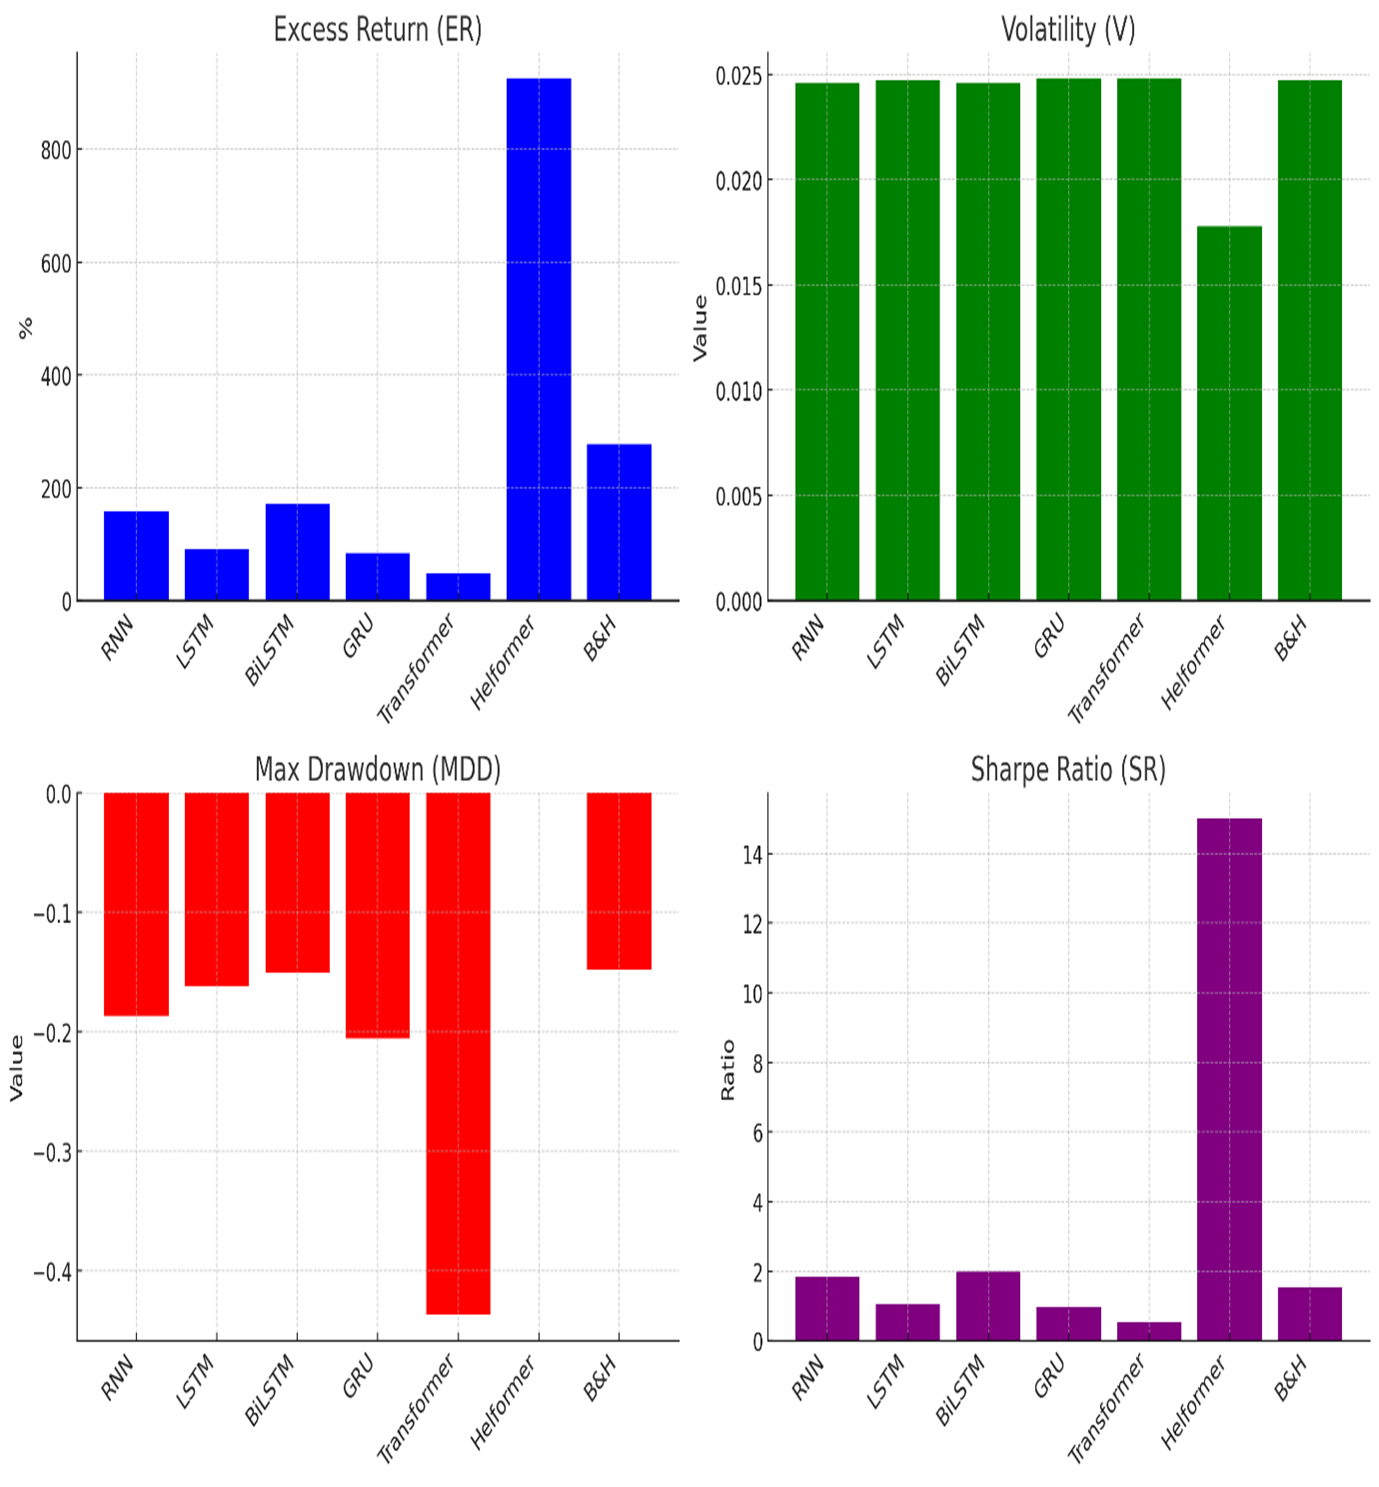 Fig. 2: Trading results.
3. Cross-Currency Generalization
Helformer’s pre-trained BTC weights transferred seamlessly to other cryptocurrencies, achieving R² > 0.99 for XRP and TRX. This suggests broad applicability without retraining—a boon for investors managing diverse portfolios.
🌍 Relevance to the Community
-
For Researchers: Helformer’s architecture opens avenues for hybrid time-series models in finance, healthcare, and climate forecasting.
-
For Practitioners: The model’s interpretable components (decomposition + attention) make it adaptable to volatile markets beyond crypto.
-
For Policymakers: Reliable price forecasts could inform regulations to stabilize crypto markets and protect investors.
🤝 Acknowledgments & Open Questions
This work wouldn’t have been possible without my brilliant co-authors Oluyinka Adedokun, Joseph Akpan, Morenikeji Kareem, Hammed Akano, and Oludolapo Olanrewaju, or the support of The Hong Kong Polytechnic University.
We’d love to hear your thoughts!
-
How might Helformer adapt to non-financial time-series data?
-
Could integrating sentiment analysis further improve accuracy?
-
What ethical considerations arise with AI-driven trading?
🔗 Access the full paper: SpringerLink | ReadCube
Kehinde Temitope is an interdisciplinary researcher and professional with a solid academic foundation in Industrial & Systems Engineering, complemented by extensive experience in data-driven research, smart manufacturing, machine learning, and financial analytics. His expertise lies in developing advanced decision support systems that integrate Data Envelopment Analysis (DEA), predictive analytics, portfolio optimization, and machine learning models for complex industrial, financial, and operational challenges. Throughout his academic and professional journey, he has demonstrated strong leadership, problem-solving, and project management capabilities, delivering impactful solutions in both academic and industry-driven settings. With proven experience across consulting, research, teaching, and collaborative industry projects, Kehinde Temitope is passionate about applying analytical rigor and innovative methodologies to optimize business processes, support informed decision-making, and contribute to sustainable organizational growth.
Follow the Topic
Related Collections
With Collections, you can get published faster and increase your visibility.
LLM-Augmented Multimodal Data Fusion for Large-Scale Data Analysis
The rapid growth of multimodal data—such as text, images, sensor streams, graphs, and structured records—has made cross-modal integration critical for modern large-scale data analysis. However, the heterogeneous nature of multimodal sources and the limitations of conventional fusion techniques hinder effective semantic alignment, representation learning, and scalable analytics.
Although large language models (LLMs) offer strong capabilities in reasoning, abstraction, and cross-domain understanding, current data pipelines still lack efficient mechanisms to incorporate LLM-driven semantics into multimodal fusion workflows. This thematic series aims to bridge this gap by exploring innovative approaches that leverage LLMs to enhance multimodal data fusion and enable more powerful, comprehensive data-driven insights.
This collection focuses on advancing LLM-Augmented Multimodal Data Fusion for Large-Scale Data Analysis, encouraging research on:
LLM-enhanced representation learning Semantic alignment across heterogeneous modalities Generative or retrieval-assisted fusion strategies Scalable system designs for real-world applications The goal is to promote new analytical paradigms where LLM-driven intelligence reshapes multimodal integration and utilization in complex scientific and industrial ecosystems.
The topics include, but are not limited to:
LLM-augmented cross-modal semantic alignment for large-scale analytics
Generative and retrieval-assisted fusion for multimodal data integration
Representation learning for heterogeneous and multi-source data fusion
Knowledge grounding and reasoning across diverse data modalities
Scalable fusion architectures for large-volume multimodal datasets
Foundation-model-assisted modality completion and data annotation
Graph–text–sensor fusion for scientific and engineering data analysis
Temporal–spatial multimodal fusion for real-world big data applications
Self-supervised learning for multimodal representation and alignment
Benchmarking, datasets, and evaluation protocols for multimodal fusion
Efficient fusion mechanisms for high-dimensional industrial and IoT data
Domain-specific multimodal fusion applications for data-driven intelligence
Publishing Model: Open Access
Deadline: Dec 20, 2026
2026 Australasian Data Science and Machine Learning (AusDM26) Special Issue
The Journal of Big Data invites submissions to a Special Issue associated with the 24th Australasian Data Science and Machine Learning Conference (AusDM 2026), to be held in Sydney, Australia, from 2–4 December 2026.
AusDM is the premier Australasian forum for researchers and practitioners in data science, data analytics, data mining, machine learning, and artificial intelligence. Since 2002, the conference has showcased advances in algorithms, systems, software, and real-world applications while fostering collaboration across academia, industry, and government.
This Special Issue welcomes substantially extended versions of selected papers presented at AusDM 2026. Submissions must include significant new research beyond the conference version, such as novel methodologies, additional experiments, expanded analyses, deeper theoretical or empirical insights, or new application studies.
Topics include, but are not limited to:
- Machine learning, deep learning, generative AI, large language models, multimodal learning, reinforcement learning, transfer learning, and federated learning
- Data mining, knowledge discovery, learning from structured, unstructured, graph, temporal, spatial, multimedia, IoT, and sensor data
- Data-centric AI, data engineering, privacy-preserving data mining, and large-scale data management
- Big data analytics, scalable and distributed machine learning, data stream mining, edge and cloud AI, and real-time analytics
- Visual analytics, explainable and interpretable AI, causal machine learning, responsible AI, fairness, transparency, and trustworthy AI
- Applications of data science and AI in business, finance, healthcare, education, agriculture, engineering, cybersecurity, environmental science, social sciences, and other domains
All submissions will undergo the journal's standard peer-review process. Invitation to submit does not guarantee acceptance.
Aligned Sustainable Development Goals (SDGs): SDG 9: Industry, Innovation and Infrastructure, SDG 4: Quality Education, and SDG 17: Partnerships for the Goals.
Publishing Model: Open Access
Deadline: Jul 26, 2027